Prototypical Reward Network for Data-Efficient RLHF
Jan 1, 2024·, ,,,·
1 min read
Jinghan Zhang
Xiting Wang
Yiqiao Jin
Changyu Chen
Xinhao Zhang
Kunpeng Liu
Abstract
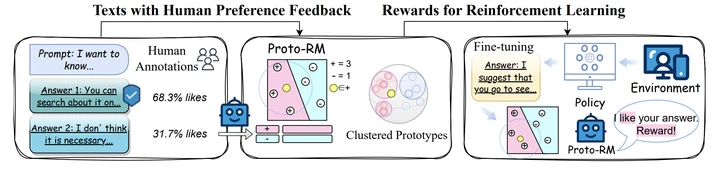
We propose a prototypical reward network that enables data-efficient reinforcement learning from human feedback (RLHF) for large language models.
Type
Publication
ACL 2024 Main Conference, Oral Presentation
Abstract
We propose a prototypical reward network that enables data-efficient reinforcement learning from human feedback (RLHF) for large language models.
Keywords
Reinforcement Learning, Human Feedback, Large Language Models, Data Efficiency
