MM-BizRAG: Rethinking Multimodal Retrieval-Augmented Generation for General Purpose Enterprise Q&A
Jul 1, 2026·,,,,, ,,,·
1 min read
Hanoz Bhathena
Parin Rajesh Jhaveri
Rohan Mittal
Prateek Singh
Aymen Kallala
Rachneet Kaur
Yiqiao Jin
Zhen Zeng
Adwait Ratnaparkhi
Denis Kochedykov
Abstract
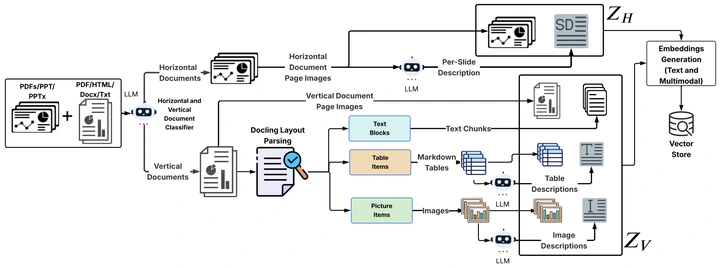
MM-BizRAG uses document structure to guide multimodal retrieval-augmented generation for enterprise Q&A. It routes report-style documents through layout-aware parsing and slide decks through page-level representations, preserves reading order during artifact transformation, and assembles multimodal context at inference time. The framework is evaluated on enterprise documents, SlideVQA, and FinRAGBench-V, and introduces FastRAGEval for measuring generative recall.
Type
Publication
ACL 2026 Industry Track
Overview
MM-BizRAG routes reports and slide decks through ingestion pipelines tailored to their structure, preserves reading order, and assembles multimodal context at inference time. It also introduces FastRAGEval, a single-call LLM judge for fine-grained generative recall.