ScreenLLM: Stateful Screen Schema for Efficient Action Understanding and Prediction

Abstract
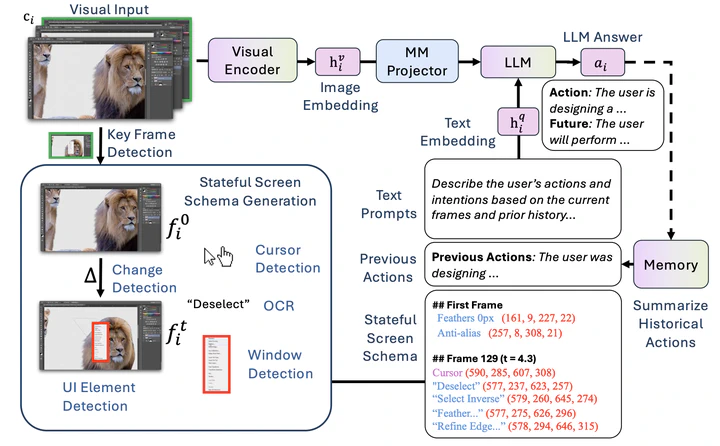
We introduce ScreenLLM, a specialized multimodal LLM for Graphical User Interface (GUI) understanding and action prediction. ScreenLLM proposes a stateful screen schema that represents dynamic user sessions as compact, time-aware textual summaries, and a high-efficiency key-frame extraction method based on second-order pixel changes to isolate significant UI transitions such as pop-up menus. Fine-tuning open-source MLLMs on high-resolution software tutorials with this schema substantially improves action prediction over strong baselines.
Type
Publication
The Web Conference 2025, MM4SG Workshop
Abstract
We introduce ScreenLLM, a specialized multimodal LLM for Graphical User Interface (GUI) understanding and action prediction. ScreenLLM proposes a stateful screen schema that represents dynamic user sessions as compact, time-aware textual summaries, and a high-efficiency key-frame extraction method based on second-order pixel changes to isolate significant UI transitions.