Beyond Structural Unification: A Perspective and Roadmap on Unified Multimodal Models
A position paper outlining five layers of functional unification for multimodal understanding and generation: inputs, representations, reasoning, optimization, and evaluation.
Sep 30, 2026
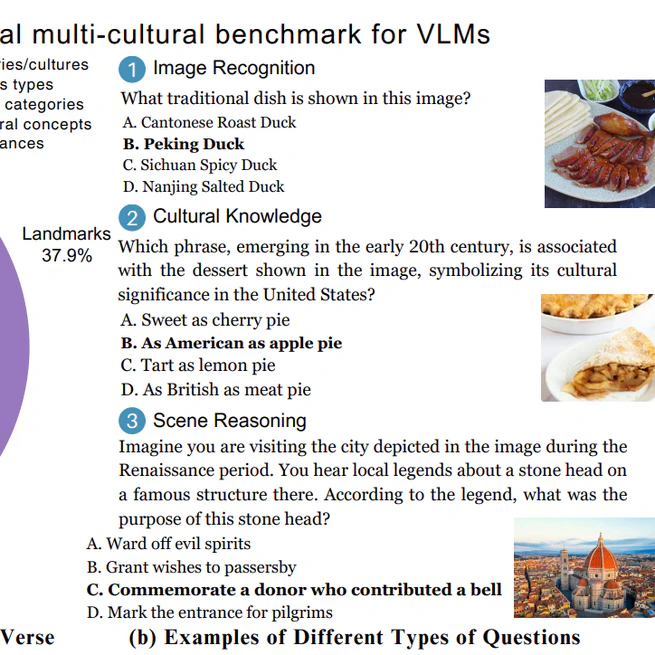
CultureVLM: Characterizing and Improving Cultural Understanding of Vision-Language Models for over 100 Countries
CultureVLM characterizes and improves cultural understanding of vision-language models across more than 100 countries using culturally-grounded benchmarks and training procedures.
Sep 1, 2026
Consistency Should Be the Priority for Unified Multimodal Models
A position paper on consistency across multimodal grounding, representations, reasoning, post-training, and evaluation.
Feb 3, 2026